How Scientists Are Teaching Machines to Understand Human Speech
In 1952 a machine at Bell Labs could recognise the digits zero to nine, spoken by one man. Seventy years on, software transcribes almost anyone, in almost any language. Almost is the interesting part.
In 1952, in a laboratory in New Jersey, a machine called Audrey listened to a man say a number. It was not much of a conversation. Audrey, built at Bell Labs by K. H. Davis, R. Biddulph and Stephen Balashek, recognised only the spoken digits zero to nine, from a single speaker. It did so by finding the formants, the resonant peaks that the mouth and throat stamp onto each vowel.
Today you can talk to your phone in a crowded kitchen and watch your words appear. The road between those two moments is one of the great quiet stories of modern science: a seventy-year argument about whether machines should understand speech the way we do, or find their own way.
Audrey, the Shoebox and the limits of rules
A decade after Audrey came IBM's Shoebox, built by the engineer William C. Dersch and named for its size. It recognised 16 words: the digits plus six commands such as "plus", "minus" and "total". In demonstrations, Dersch would dictate a sum such as "seven plus three plus six plus nine plus five, subtotal", and the machine, wired to an adding machine, printed the answer: 30. It was shown on television and at the 1962 Seattle World's Fair, and it needed only 31 transistors.
The Shoebox sorted sounds into "machine vowels" from the throat and hissing "machine consonants", and identified each word by its pattern. That was the spirit of the age: engineers described the rules of speech, then built circuits to follow them. It worked for tiny vocabularies and patient, practised speakers. It did not scale.
Progress was uneven. In 1969 the Bell Labs engineer John R. Pierce published a critical open letter about speech-recognition research, and funding at Bell Labs stalled for years. In 1971 the American defence research agency DARPA launched a five-year programme with a target vocabulary of at least 1,000 words, a bold leap from 16.
The statistical turn
The breakthrough was a change of philosophy. At Carnegie Mellon University in the 1970s, James and Janet Baker began applying hidden Markov models (HMMs), mathematics developed by Leonard Baum and colleagues in the late 1960s, to speech. At IBM, Frederick Jelinek's group took a similarly statistical approach and, by the mid-1980s, had built Tangora, a voice-operated typewriter with a 20,000-word vocabulary. Jelinek told IBM's THINK magazine in 1987 that it was wrong to ask a machine to imitate people.
An HMM treats speech as a chain of hidden states, roughly the sounds being formed, each producing acoustic evidence with some probability. Rather than hand-writing rules, engineers let the model learn those probabilities from recorded speech, then searched for the most likely sequence of words. A language model, which estimates how likely each word is to follow the last few, kept the guesses grammatical. Lawrence Rabiner of Bell Labs set out the method in a celebrated 1989 tutorial, and by then HMMs had become the dominant approach. They would remain so for more than two decades.
A seventy-year argument about whether machines should understand speech the way we do, or find their own way.
Deep learning finds its voice
The next shift came from neural networks. Around 2009 Geoffrey Hinton's students at the University of Toronto and Li Deng's team at Microsoft Research began using deep networks to model the acoustics of speech. In 2012, Hinton, Deng and colleagues published a joint paper in IEEE Signal Processing Magazine setting out the shared views of four research groups. Their message was blunt: deep networks with many layers were outperforming the statistical models that had dominated acoustic modelling, on several benchmarks and often by a wide margin.
Then, in 2017, Google researchers introduced the transformer, an architecture built on "attention" that lets every part of an input look at every other part.
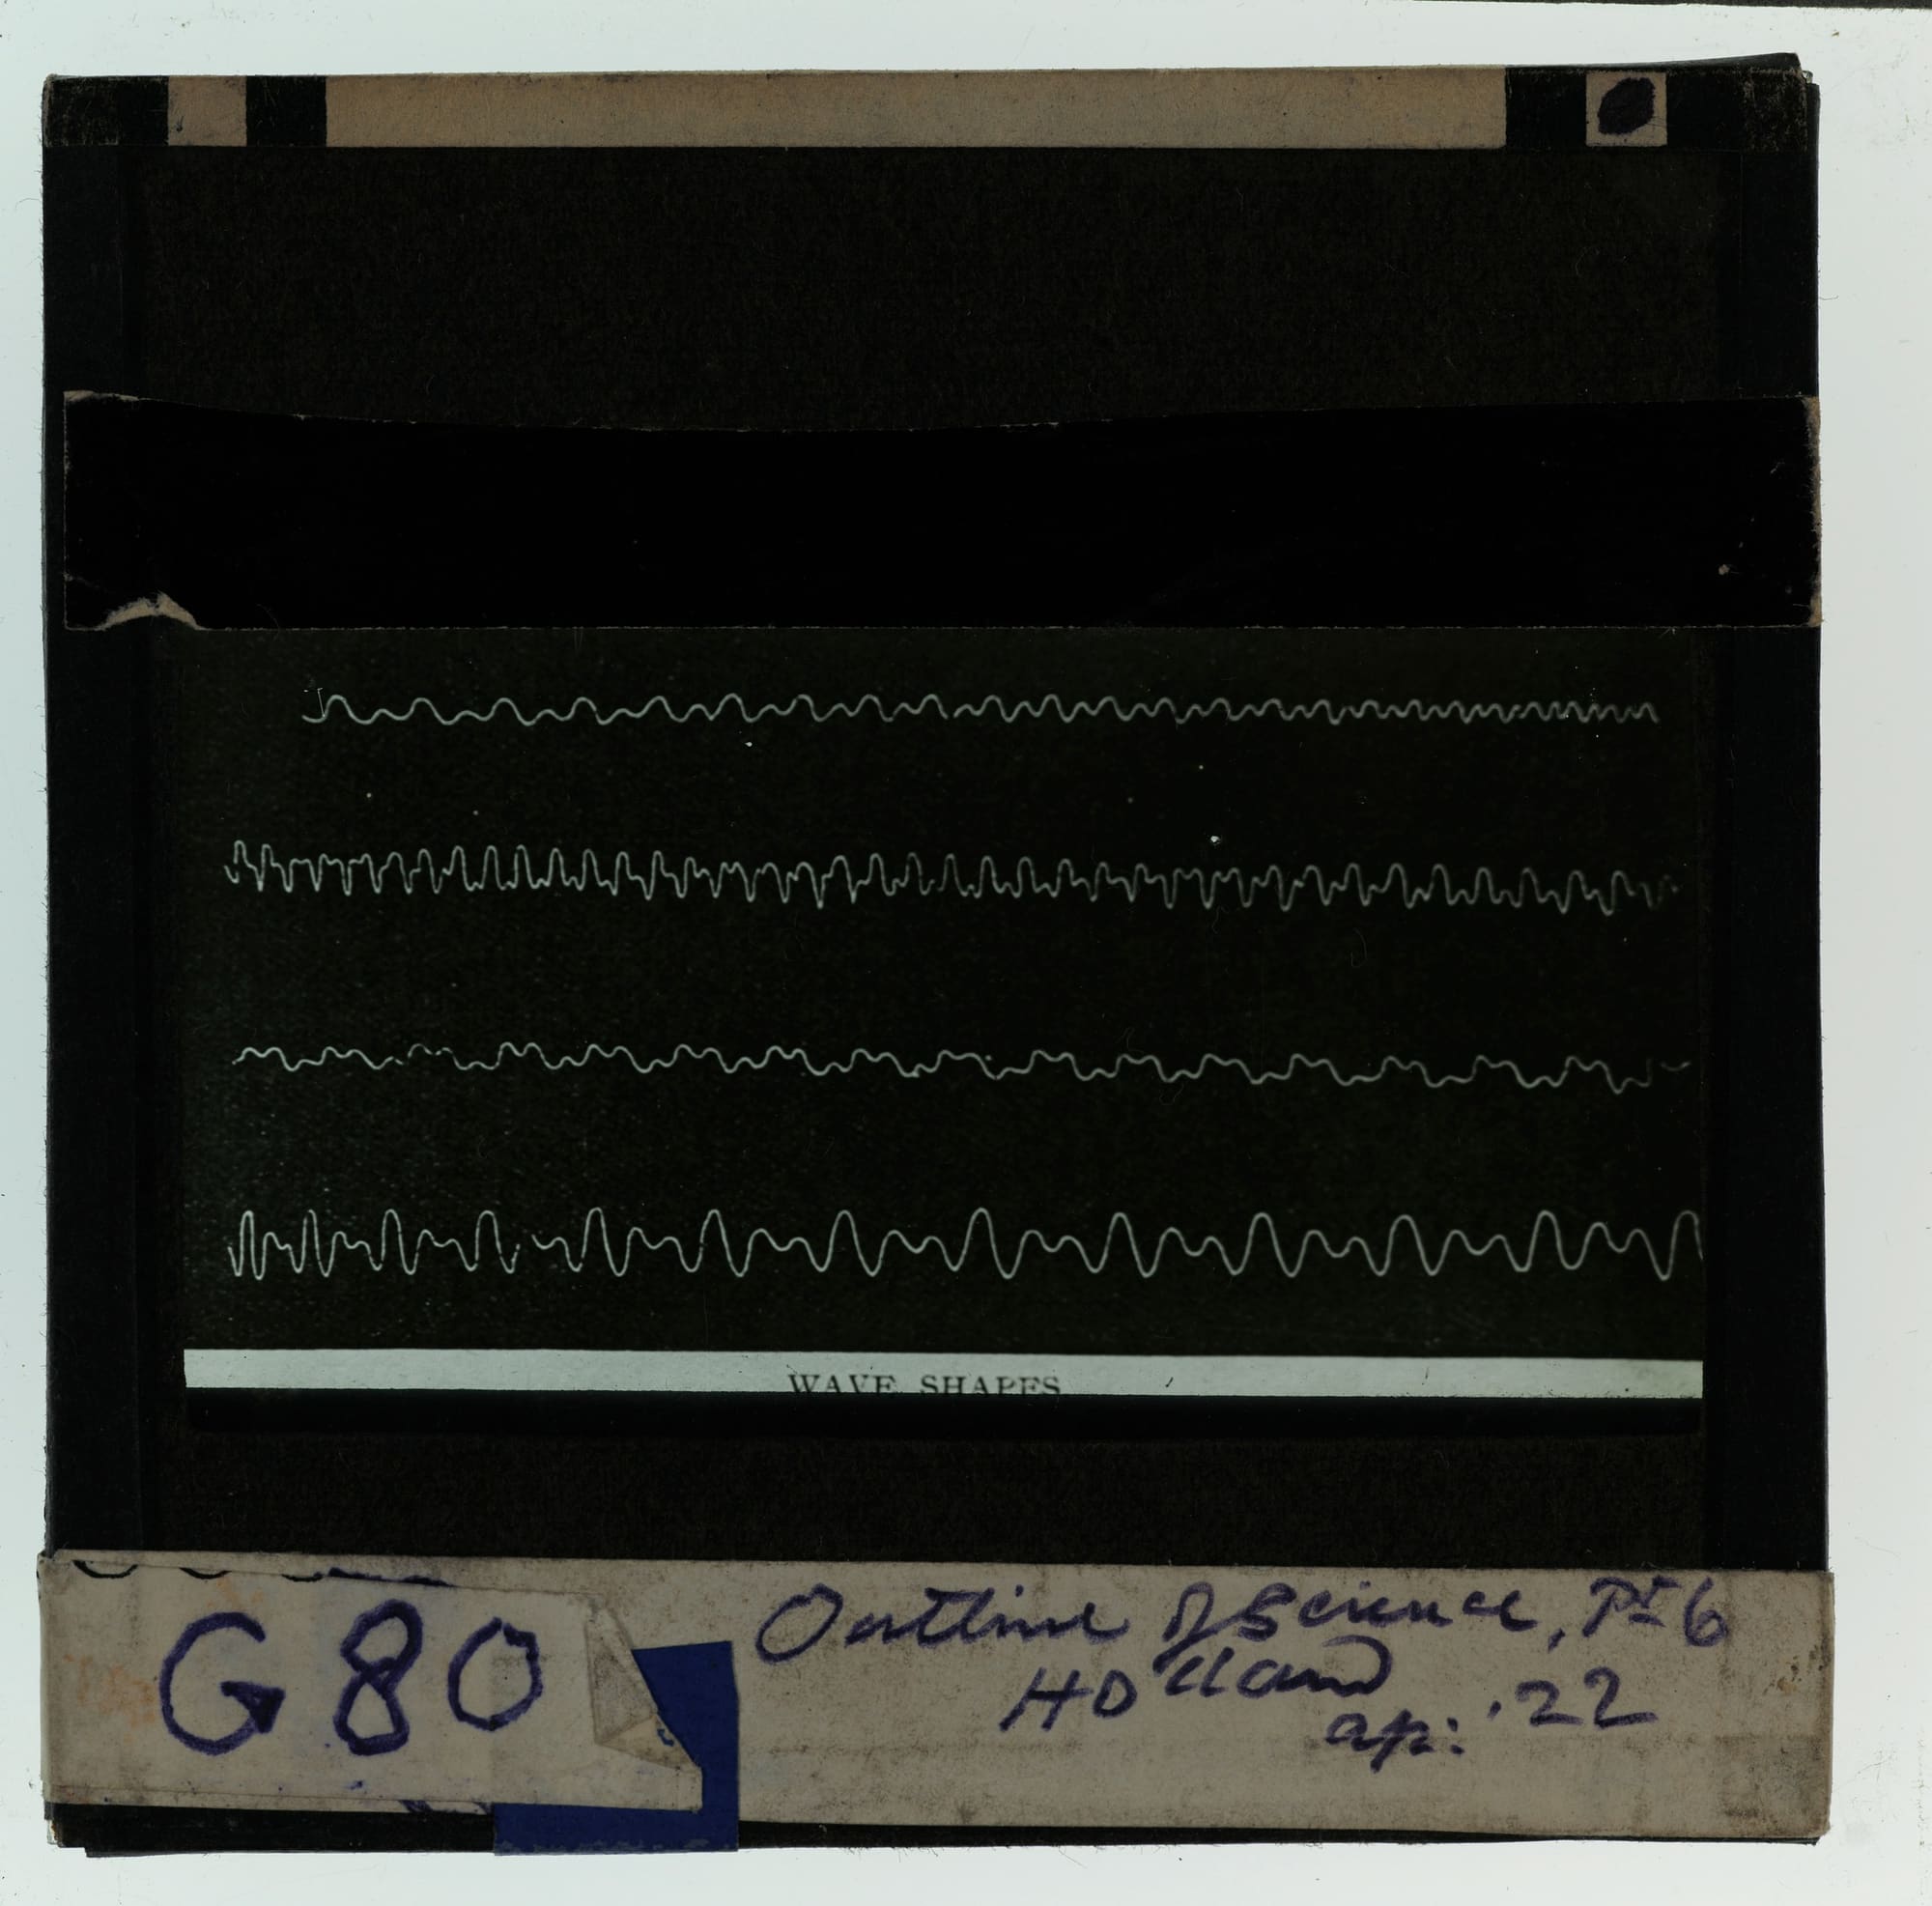
In 2022 OpenAI released Whisper, a transformer trained on 680,000 hours of audio collected from the web, covering many languages and tasks including translation. Whisper chops audio into 30-second windows, turns each into a log-Mel spectrogram (a picture of sound energy across pitch and time), and generates the transcript word by word. Without any fine-tuning, it often matched systems trained on specific benchmarks, and OpenAI reported it made 50 per cent fewer errors than models specialised on the popular LibriSpeech test when measured across many diverse datasets. The models were released openly, in sizes from 39 million to 1.55 billion parameters.
Learning without labels
Whisper's lesson was that scale and variety matter. A different line of research asked how little human help a machine needs.
Transcribed speech is expensive: someone must listen and type. Raw audio is cheap. wav2vec 2.0, published in 2020 by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed and Michael Auli at Facebook AI, learns from untranscribed recordings by hiding stretches of the sound and training the network to identify what was missing, a little like a fill-in-the-blanks exercise for audio. Only afterwards is it fine-tuned on a small amount of transcribed speech.
The results were remarkable. Pre-trained on 53,000 hours of unlabelled audio and fine-tuned on just ten minutes of transcribed speech, it achieved word error rates of 4.8 per cent on LibriSpeech's clean test set and 8.2 per cent on the harder one. With one hour of labels it beat the previous best system trained on 100 hours. That matters enormously for the thousands of languages that will never have vast transcribed archives.
:::note The numbers
- 1952: Audrey recognises 10 spoken digits from one speaker
- 1962: IBM's Shoebox understands 16 words
- Mid-1980s: IBM's Tangora handles a 20,000-word vocabulary
- 2020: wav2vec 2.0 reaches 4.8% word error with 10 minutes of labelled speech
- 2022: Whisper trains on 680,000 hours of web audio :::
Who still gets misheard
For all this progress, machines do not hear everyone equally. In 2020, Allison Koenecke and colleagues at Stanford University tested five commercial speech-recognition systems, from Amazon, Apple, Google, IBM and Microsoft, on interviews with Black and white Americans matched for age and gender. The average word error rate was 0.35 for Black speakers and 0.19 for white speakers. The gap came mainly from the acoustic models, not the vocabulary, which suggests the systems had learned from too little of some ways of speaking.
Age matters too. Ravichander Vipperla, Steve Renals and Joe Frankel at the University of Edinburgh tracked speakers over years using recordings of the US Supreme Court, and found that error rates for older voices were significantly higher than for younger adults and rose gradually with age. Adapting the system to each speaker narrowed the gap but did not close it. Their later work found slower speaking rates played a part, while changes in pitch made little difference.
And then there is noise, the oldest enemy. The CHiME-6 challenge recorded twenty real dinner parties in people's homes, with four friends cooking, eating and chatting while microphone arrays listened from around the room. The official baseline system misrecognised around half the words. Overlapping talkers, clattering pans and distance from the microphone remain hard, much as they are for people with hearing loss.
The machines have come a long way from Audrey. But the measure of success is no longer whether a computer can understand one careful voice in a quiet lab. It is whether it can understand your grandmother, across the table, while the kettle boils.
Sources & further reading
- Radford et al., "Robust Speech Recognition via Large-Scale Weak Supervision" (Whisper), arXiv:2212.04356
- Baevski et al., "wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations", arXiv:2006.11477
- Vaswani et al., "Attention Is All You Need", arXiv:1706.03762
- Hinton et al., "Deep Neural Networks for Acoustic Modeling in Speech Recognition", IEEE Signal Processing Magazine (2012)
- IBM History: Speech recognition and the Shoebox
- Rabiner, "A Tutorial on Hidden Markov Models and Selected Applications in Speech Recognition" (1989)
- Koenecke et al., "Racial disparities in automated speech recognition", PNAS (2020)
- Vipperla, Renals and Frankel, "Longitudinal study of ASR performance on ageing voices" (2008)
- "CHiME-6 Challenge: Tackling Multispeaker Speech Recognition for Unsegmented Recordings", arXiv:2004.09249
- OpenAI: Introducing Whisper
- OpenAI Whisper on GitHub
Filed under Technology. Spotted an error? Tell the editors.